Agent skills as trainable parameters
November 5, 2026 2026-11-05 8:14Agent skills as trainable parameters
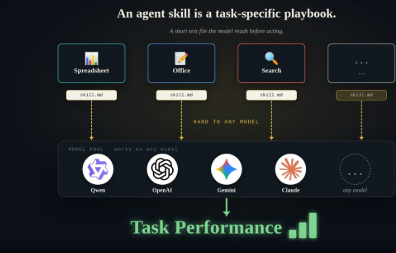
SkillOpt organizes skill editing as a forward–backward–update cycle in text space. In the forward pass, the frozen target model executes a batch of training tasks with the current skill; the rollout batch size controls how much evidence each update receives. In the backward pass, a separate optimizer model reads the resulting trajectories in reflection minibatches, distilling patterns to preserve from successful trajectories and patterns to correct from failures.
In the update step, the optimizer proposes small add, delete, and replace edits; candidate edits are merged, deduplicated, ranked, and clipped by a textual learning rate—a per-step edit budget. Every candidate skill must then pass a strict validation gate: it is adopted only if it scores strictly higher than the current skill on the held-out validation split.
Rejected edits are not discarded; they enter a rejected-edit buffer that serves as negative feedback for later optimizer calls in the same epoch. On a slower cadence, an epoch-wise slow/meta update consolidates longer-horizon lessons that single batches cannot reveal (Figure 2). Together, bounded edits, validation gating, and best-version selection keep skill optimization controllable and auditable, so the skill converges instead of drifting.